CrossPascal Early Access 019
Run models without installing Python.

Windows x64 | Delphi 13.2 | Lazarus 4.8

EA019 · Ready CUDA models. Prepare can download a CPU or CUDA bundle for your PC. Pascal runs both through TVM. Inference and conversion run without Python.

Language models | Local chat

Keep your app.
Add a model.

Bring local chat into your Delphi or Lazarus app with Qwen or Gemma. Generate text, ask about a photo, and keep inference on your own computer.

Text + image is available: Qwen2.5-VL 3B and Gemma 3n E4B on CPU or CUDA. Dense Qwen2.5 and Gemma 2 remain text-only. Compare supported inputs.

Compare language model families
Recorded output | QwenChat

Qwen2.5-Coder-0.5B-Instruct

This is a CUDA text recording. Prepare QwenChat downloads a different model: Qwen2.5-VL 3B with text and image input, on CPU or CUDA.

The recorded checkpoint uses Apache-2.0. The prepared Qwen-VL model uses the Qwen Research License. Compare licenses.

Native TVM. The CUDA text profiles and both prepared Qwen2.5-VL variants run directly from Pascal.

RTX 4060 Ti | CUDA sm_89 | Delphi 13.2

The first recording ends naturally. The other two show generation stopping at a token limit.

Compare a complete answer with token-limit examples

Prompt | Say hello in English and ask a short question.

Hello! How can I assist you today?
Stop | End of sequence

Prompt | Say hello in English and ask a short question.

Hello! How can I assist
Stop | Manual token limit

Prompt | Print the integers from 1 through 300 in order, separated by commas. Do not add any introduction or stop early. Begin with 1, 2, 3, 4, 5.

1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16, 17, 18, 19, 20, 21, 22, 23, 24, 25, 26, 27, 28, 29, 30, 31, 32, 33, 34, 3
Stop | Token limit example

These are saved recordings. In the apps, 0 uses automatic output; set a positive limit or press Stop.

Gemma 3n E4B

Gemma Terms and the Prohibited Use Policy apply.

Native TVM. Gemma runs directly from Pascal, including image input for Gemma 3n on CPU and CUDA. On CPU, an image prompt can take several minutes.

Choose an input example
Recorded text run | GemmaChat
Lazarus 4.8 | TVM CUDA | RTX 4060 Ti

Prompt | What is the capital of France? Answer with the city name only.

Paris

This recording uses CUDA. Prepare GemmaChat sets up the CPU version.

Recorded CPU run | EA017 ImagePrompt
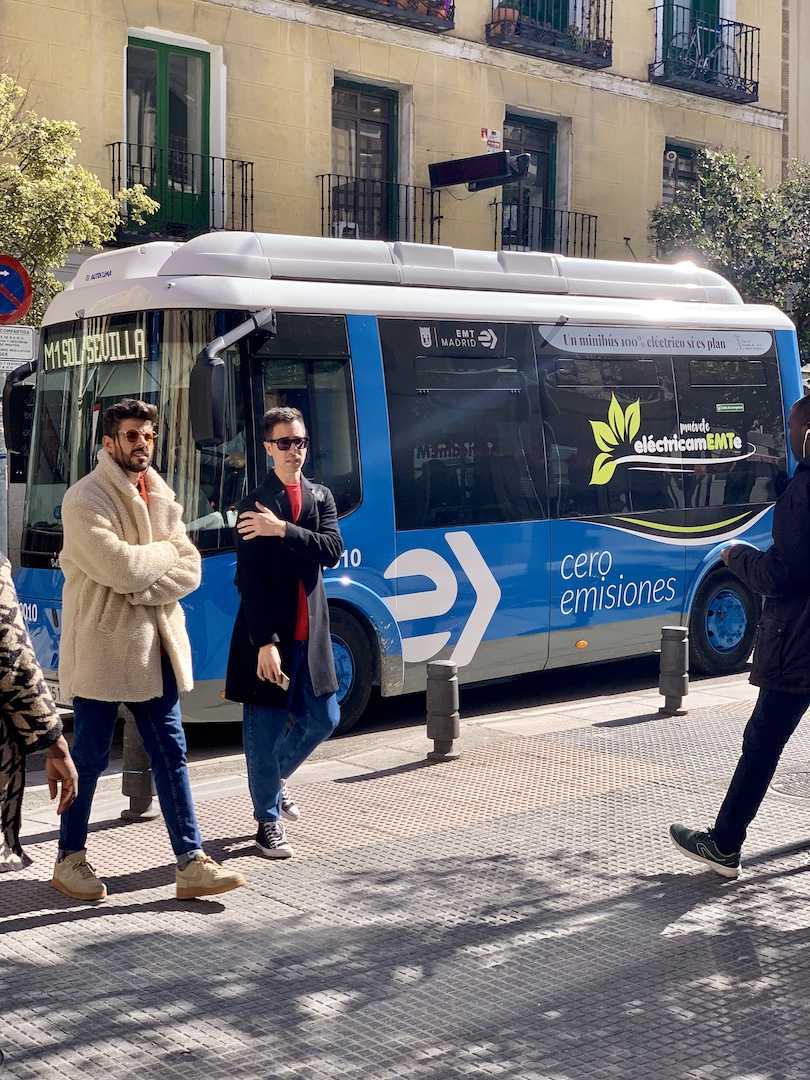
Input photo: a blue and white bus on a city street
Gemma 3n E4B | Lazarus 4.8
The main object in this image is a blue and white electric bus parked on a city street, with several people standing nearby.

ImagePrompt ran with Gemma 3n for this recording. Its Prepare script sets up Qwen2.5-VL 3B. Try Gemma 3n in GemmaChat.

Prepared model: Qwen2.5-VL 3B | CPU or CUDA. CPU: about 24 GiB RAM and AVX2 + FMA.

For other Qwen models, see Qwen2.5 Instruct and Coder. These text-only models require conversion for an NVIDIA GPU.

The starter uses Qwen-VL 3B under the Qwen Research License for non-commercial research and evaluation. Commercial use needs a separate license. Built with Qwen.

Start here / Two ways to run
Available in EA019
CPU | Windows x64 | Ready to run

Prepare. Open. Run.

Start with Qwen2.5-VL 3B or Gemma 3n E4B. Prepare sets the project paths and downloads the model and sample image. To select CPU explicitly, run Prepare.cmd -Device CPU.

  1. 01Download a preparation ZIP below, extract it, and run Prepare.cmd.
  2. 02Wait for READY. In the folder it opens, open the .dproj in Delphi 13.2 or the .lpi in Lazarus 4.8.
  3. 03Select Windows 64-bit and Run. In the chat, select Load model, then Generate.

Qwen-VL 3B: non-commercial research and evaluation under the Qwen Research License; commercial use needs a separate license. Built with Qwen. Gemma 3n: Gemma Terms and its use restrictions apply.

Prepare QwenChatCPU 5.4 GiB · CUDA 4.1 GiBPrepare GemmaChatCPU 11.5 GiB · CUDA 8.6 GiB
First run: access, storage and IDE steps
  1. The repositories and releases are public. Prepare downloads without a GitHub account or token. If GitHub limits anonymous requests, you can retry with an optional GitHub CLI login or token. Token input is hidden; saving it in Windows Credential Manager is optional.
  2. Keep the extracted preparation files together. Prepare downloads a portable runtime; you do not need to install Python, copy DLLs or convert a model. It verifies checksums and resumes interrupted package downloads.
  3. On CPU, Qwen-VL needs about 24 GiB RAM and a 5.2 GiB model download; Gemma 3n needs about 32 GiB RAM and an 11.4 GiB model download. These two CPU bundles require AVX2 and FMA (Haswell-compatible or newer). Plan for 45 GiB of free disk space for Gemma 3n, including the download and extracted files. Prepare checks free disk space first.
  4. The default install is %LOCALAPPDATA%/CrossPascal/early-access-019. To use another drive, set CROSSPASCAL_PREPARE_HOME before starting. Models and cached downloads are shared between examples.
  5. Open the prepared project, select Release and Windows 64-bit, then Run. The model, SDK and sample-image paths are already filled in. In either chat, select Load model and Generate; Stop requests cancellation and Unload releases the model.

Read the complete preparation guide for all 13 projects, model terms, storage and troubleshooting.

The scripts share downloaded files, preserve edits to SDK sources and keep your existing settings. CPU image requests can take minutes. All supplied Pascal executables are built with Lazarus.
Available in EA019
GPU | NVIDIA CUDA | Ready to run

Run on CUDA.

The same Prepare ZIP works for CPU and CUDA. Prepare checks the NVIDIA driver, compute capability and free GPU memory. It prints which bundle it will download and why.

  1. 01Extract the QwenChat or GemmaChat preparation ZIP.
  2. 02Run Prepare.cmd, or add -Device CUDA to require CUDA.
  3. 03Open the prepared project. Run it, select Load model, then Generate.

Use a driver that supports CUDA 12.8. A card with 8 GiB of VRAM is a good starting point for these language models. Free memory can be lower while other apps use the GPU.

Prepare QwenChatCPU 5.4 GiB · CUDA 4.1 GiBPrepare GemmaChatCPU 11.5 GiB · CUDA 8.6 GiB

EA019 downloads are publicly available without a GitHub account. Model licences and hardware requirements are listed with each bundle. This page shows recorded examples; inference runs locally in the desktop apps.

Six small Pascal examples.

Six ready-to-run examples, from loading a model to image prompts.View examplesHide examples

Each button downloads its preparation script. Extract the ZIP, run Prepare.cmd, then open the prepared project and Run. These console examples use the same API as QwenChat and GemmaChat. Five use Gemma 2 under Gemma Terms; ImagePrompt uses Qwen-VL 3B under the non-commercial Qwen Research License.

  1. 01Prepare LoadUnloadFirst run: about 3.8 GiBInspect, load and unload a model.
  2. 02Prepare GenerateTextFirst run: about 3.8 GiBSubmit a prompt and receive the answer.
  3. 03Prepare GenerationSettingsFirst run: about 3.8 GiBSet the supported generation parameters.
  4. 04Prepare StreamAndStopFirst run: about 3.8 GiBRead text as it arrives and stop generation.
  5. 05Prepare RepeatedRequestsFirst run: about 3.8 GiBReuse loaded weights across independent requests.
  6. 06Prepare ImagePromptFirst run: about 5.4 GiBAsk about an image with a compatible model.

All generation examples accept an image when the selected bundle supports it. LoadUnload demonstrates lifecycle only.

Repository map

Use the parts you need.

Five repositories. See how they fit together.View repository mapHide repository map

Find the right source repository, see how the parts connect, and choose what belongs in your application. Five code repositories form the toolkit; the website is separate.

Model preparation

Converter

crosspascal-convert

Turn a supported checkpoint into a native model bundle.

model bundle
Applications & shared Pascal code

CrossPascal

crosspascal

AI examples, image adapters, and algorithms. Each feature uses the libraries it needs.

QwenChat | GemmaChat | VisionModels | MarkerLite
Model & tensor execution

TVM

crosspascal-tvm

Load native modules, exchange tensors, and call compiled functions from Pascal.

Apache TVM | TVM FFI | DLPack
Images & video

OpenCV

crosspascal-opencv

Process images, use native Mat buffers, and read or write video through CrossCV.

OpenCV + contrib | CrossCV bridge
Document images

Leptonica

crosspascal-leptonica

Create and transform Pix images, convert pixel formats, and prepare scans for processing.

Leptonica | image codecs
AI is optional.

OpenCV, Leptonica, and TVM are ready-to-use libraries for your own Pascal applications. AI features depend on them; the libraries do not require the AI features or the converter. Each library uses its matching native runtime.

Points to a library being used A model bundle moves between toolsDependencies vary by feature.
Dependency details & website repositories

Choose a route

OpenCV and Leptonica can each be used without TVM, the converter, or an AI model. The TVM interface can be reused without the CrossPascal demo applications; its current Pascal unit also needs OpenCV type declarations.

The converter and Pascal consumers use the same pinned Apache TVM / TVM FFI runtime. A ready model bundle lets you skip conversion. Pure Pascal geometry and set algorithms need none of these native runtimes.

Read the TVM dependency notes

The website lives separately

crosspascal-homepage (private)
Homepage source and design staging. GitHub access required.
crosspascal-live
The published GitHub Pages website you are reading.

Neither website repository is needed to build or run a Pascal application. Other and archived projects are outside this SDK dependency map.

Browse all repositories by the author
Other public repositories | outside this SDK

Formulas and plots

graphbuilder-npp uses pascal-crossgraph and pascal-mathparser. The plotting engine also depends on the parser.

mathparser-live is their website, with a WebAssembly build of the parser.

nashira3d uses the parser for 3D surface plots. nashira3d-live presents the project and runs its surface core in the browser.

Upstream work and directories

tvm-ffi is a fork of Apache TVM FFI. The current CrossPascal SDK installs the official upstream package, so this fork is not a required checkout.

nppPluginList and awesome-pascal are directory forks. pisarev holds the GitHub profile. None is a CrossPascal runtime dependency.

Archived projects remain in the full repository list.

AI is optional. OpenCV, Leptonica and TVM can also be used on their own.

Explore more models.Green: available in EA019. Grey: examples pending or planned.Model catalog

Each available card shows how to run the model in EA019. Prepare supplies CPU and CUDA bundles for the language and vision examples. Dense Qwen text checkpoints can also be built with the converter. Example pending means the example is still in preparation. Planned marks roadmap work. Public downloads require no GitHub account.

Available in EA019Bus photo used in the Qwen-VL CPU acceptance run
CPU / CUDA | Text + image

Qwen2.5-VL 3B

Qwen Research License | Non-commercial research and evaluation. Built with Qwen.

Ask about a photo in either chat app. The ready CPU and CUDA bundles include vision and text libraries. The checked 224-pixel profile is intended for simple visual questions.

Available in EA019
"Paris"
CUDA | Text | Recorded output

Gemma 3n E4B

Gemma Terms and the Prohibited Use Policy apply.

Runs on CPU or CUDA. Image prompts need a matching vision projector. Prepare supplies matching text and image libraries for CPU and CUDA. The app streams text and keeps the model loaded between prompts.

Example and setup
Available in EA019
Gemma 2 2B
CPU / CUDA | Text only | Experimental profile

Gemma 2 2B

Gemma Terms and use restrictions apply.

Try short text completions on CPU or CUDA. This experimental profile approximates part of the attention calculation; its output can differ from the original model. It accepts text only; long-context use has not been validated. Read the profile limits.

Download CPU bundle and read its scope
Available in EA019 vancyclist
CPU / CUDA | Illustration

YOLO11n detection

AGPL-3.0 | Licensing for proprietary use.

Find objects and return boxes, class IDs and scores in VisionModels. Prepare downloads a CPU or CUDA model with its matching source and licence.

Prepare VisionModelsFirst run: about 800 MiB
Available in EA019 TOP LABELtypewriter
CPU / CUDA | Illustration

YOLO11n classification

AGPL-3.0 | Licensing for proprietary use.

Rank image classes in VisionModels using the ready model and its declared profile.

Prepare VisionModelsFirst run: about 800 MiB
Available in EA019 fishing boatrowboat
CPU / CUDA | Illustration

RT-DETR R18vd

Run the pinned object detector in VisionModels. The setup guide covers source download, conversion and the Pascal application.

Prepare VisionModelsFirst run: about 800 MiB
Available in EA019 TOP LABELFrench horn
CPU / CUDA | Illustration

SqueezeNet 1.1 and ResNet50

Compare two image classifiers using the same Pascal example and the supplied source profiles.

Prepare VisionModelsFirst run: about 800 MiB
Example pending
Internal runs | Illustration

YOLO segmentation

Pixel masks for individual objects. Internal model runs exist; the supported example and model package are being prepared.

Example pending
YOLO pose and oriented boxes
Internal runs

YOLO pose and oriented boxes

Show keypoints and rotated object boxes. These task types have internal YOLO11 results; packaged GUI examples are planned.

Example pending
More YOLO generations
Internal runs | Selected representatives

More YOLO generations

Internal checks span v3u, v5/v5u, v8, v9, v10, v11, v12 and v26. Downloadable profiles will identify the exact model and task tested.

Example pending
Internal run | Illustration

PaddleOCR PP-OCRv5

Detect text regions and read their contents. A complete downloadable OCR example is being prepared; the OCR tab shows an engineering preview.

Example pending TEXT QUERYred umbrella
Internal evidence | Illustration

OmDet

Text-guided object detection has been checked in two Windows CPU test cases. Its numerical outputs differ from the reference model. A downloadable example is still pending. Read the checked scope.

Example pending
Internal conversion | Illustration

BiRefNet Lite

Separate a foreground object from its background. The Lite model has been converted internally; a ready-to-run example is still pending.

Example pending
DeepLabV3 and MobileNetV2
Internal runs

DeepLabV3 and MobileNetV2

Semantic segmentation and image classification have internal results. Current-SDK examples and complete user setup are still pending.

Planned Query | yellow pear
Roadmap | Illustration

Grounded-SAM

Use a text query to guide object selection and segmentation. This is a roadmap direction; no working EA019 example is claimed.

Go further

Build it into your own app.

Library APIs and ready-to-run examples

Start with the matched SDK. It groups the five projects from the same release. You can also use the library bindings in your own Pascal applications.

Versions match this release. The counts describe binding names. Runtime validation covers the scenarios listed in each project's documentation.

Try an image or native-library example with the same preparation steps:

Prepare all 13 examplesPer example: 170 MiB to 11.5 GiBRead the setup guide
Check compatibility, validation, and the roadmap

This release was tested on Windows x64 with Delphi 13.2 and Lazarus 4.8. This release uses Windows DLLs. Linux shared libraries (.so) are outside its verification matrix. Separate engineering runs, including PaddleOCR, have their own scope.

Preparation, downloads and first-run help

Prepare.cmd downloads the SDK, native libraries and a compatible CPU or CUDA bundle for the selected example. It verifies the files and sets the project paths.

Downloads are verified and shared across examples. Interrupted package downloads can resume. With an empty cache, all 13 examples need about 21.0 GiB in CPU mode or 16.2 GiB in CUDA mode, plus space for extracted files. You can prepare just one example. Check model and library licenses before use.

CUDA requirements. Prepare ships bundles for compute capability 6.1, 7.5, 8.6, 8.9 and 12.0. The driver must support CUDA 12.8. An RTX 4060 Ti ran the language and vision examples. A GTX 1650 ran all five vision profiles. The remaining targets were checked at build time. Prepare prints its memory check before downloading the model. Use -Device CPU to choose CPU.

Early Access | EA019

Source code and release downloads are public. Prepare needs no token; an optional GitHub sign-in can raise the request limit. SDK & examples | CPU model bundles

Licenses and redistribution

Check the terms for your model.

Model and library terms differ. Review the terms before downloading or redistributing.Review licensesHide licenses

Original CrossPascal code uses MIT. Model weights, converted model bundles, native libraries and their dependencies retain their own licenses. Choose the terms that fit your application before downloading or redistributing them.

CrossPascal source

MIT covers original code and documentation. The Binarize and Curve units retain MPL 1.1 and their original attribution. Other third-party notices remain applicable.

Qwen models

Qwen2.5-VL 3B Instruct, downloaded by QwenChat and ImagePrompt, uses the Qwen Research License for non-commercial research and evaluation. Commercial use needs a separate license from Alibaba Cloud. Built with Qwen.

The dense Qwen2.5 0.5B/1.5B and Coder 0.5B checkpoints shown here use Apache-2.0. Check the exact checkpoint; licenses differ across the family.

Gemma 2 and Gemma 3n

The Gemma Terms of Use and Prohibited Use Policy apply to these models and derivatives. Bundles include the terms, NOTICE, modification records and redistribution guidance.

When redistributing, retain these files, mark changes and carry the use restrictions into your distribution agreement.

OpenCV and FFmpeg

OpenCV uses Apache-2.0 with separate dependency notices. This CrossCV build statically links LGPL-2.1-or-later FFmpeg. Keep the matching sources available with the binary and follow the included RELINKING.md for a full-source rebuild with modified FFmpeg.

Matching OpenCV / FFmpeg sources and notices. OpenCV nonfree algorithms can carry separate patent considerations.

The bus photograph is the original Ultralytics sample, accompanied by its upstream AGPL-3.0 notice. Use images you have the right to use in your own application. Keep every supplied license, copyright notice and modification record when redistributing a package.